
Apache Spark is an open-source distributed computational framework that is created to provide faster computational results. It is an in-memory computational engine, meaning the data will be processed in memory.
Spark supports various APIs for streaming, graph processing, SQL, MLLib. It also supports Java, Python, Scala, and R as the preferred languages. Spark is mostly installed in Hadoop clusters but you can also install and configure spark in standalone mode.
In this article, we will be seeing how to install Apache Spark in Debian and Ubuntu-based distributions.
Install Java and Scala in Ubuntu
To install Apache Spark in Ubuntu, you need to have Java and Scala installed on your machine. Most of the modern distributions come with Java installed by default and you can verify it using the following command.
$ java -version

If no output, you can install Java using our article on how to install Java on Ubuntu or simply run the following commands to install Java on Ubuntu and Debian-based distributions.
$ sudo apt update
$ sudo apt install default-jre
$ java -version
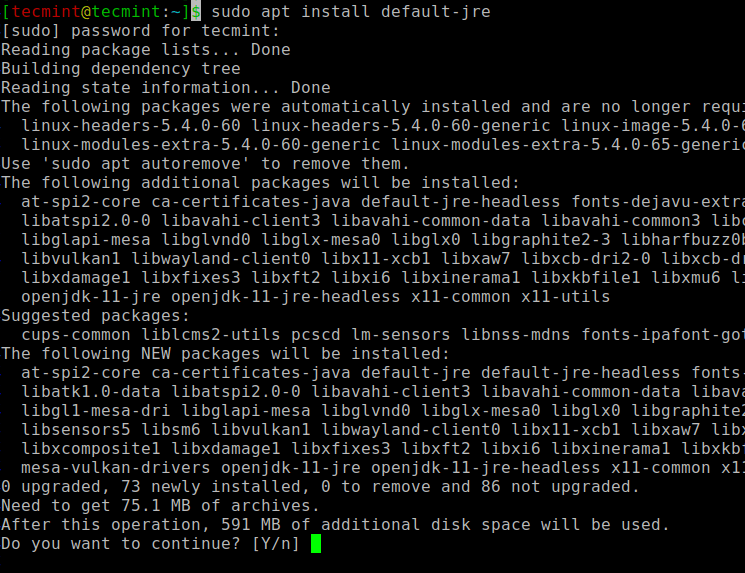
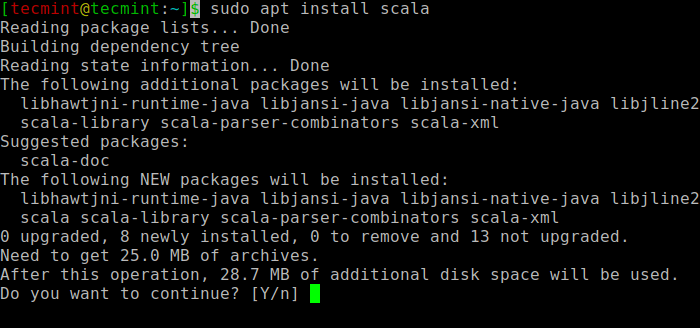
Next, you can install Scala from the apt repository by running the following commands to search for scala and install it.
$ sudo apt search scala  ⇒ Search for the package
$ sudo apt install scala ⇒ Install the package
To verify the installation of Scala, run the following command.
$ scala -version

Scala code runner version 2.11.12 -- Copyright 2002-2017, LAMP/EPFL
Install Apache Spark in Ubuntu
Now go to the official Apache Spark download page and grab the latest version (i.e. 3.1.1) at the time of writing this article. Alternatively, you can use the wget command to download the file directly in the terminal.
$ wget https://apachemirror.wuchna.com/spark/spark-3.1.1/spark-3.1.1-bin-hadoop2.7.tgz
Now open your terminal and switch to where your downloaded file is placed and run the following command to extract the Apache Spark tar file.
$ tar -xvzf spark-3.1.1-bin-hadoop2.7.tgz
Finally, move the extracted Spark directory to /opt directory.
$ sudo mv spark-3.1.1-bin-hadoop2.7 /opt/spark
Configure Environmental Variables for Spark
Now you have to set a few environmental variables in your .profile file before starting up the spark.
$ echo "export SPARK_HOME=/opt/spark" >> ~/.profile
$ echo "export PATH=$PATH:/opt/spark/bin:/opt/spark/sbin" >> ~/.profile
$ echo "export PYSPARK_PYTHON=/usr/bin/python3" >> ~/.profile
To make sure that these new environment variables are reachable within the shell and available to Apache Spark, it is also mandatory to run the following command to take recent changes into effect.
$ source ~/.profile
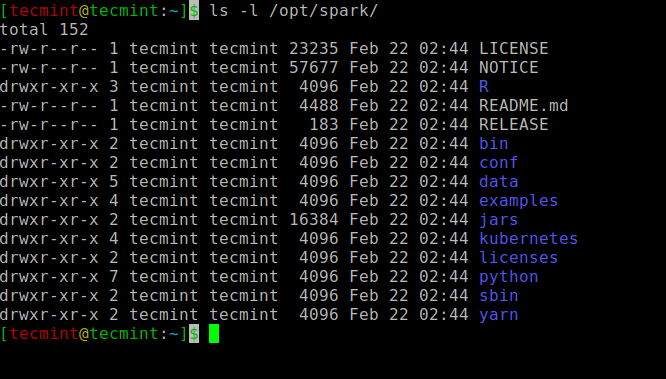
All the spark-related binaries to start and stop the services are under the sbin folder.
$ ls -l /opt/spark
Start Apache Spark in Ubuntu
Run the following command to start the Spark master service and slave service.
$ start-master.sh
$ start-workers.sh spark://localhost:7077
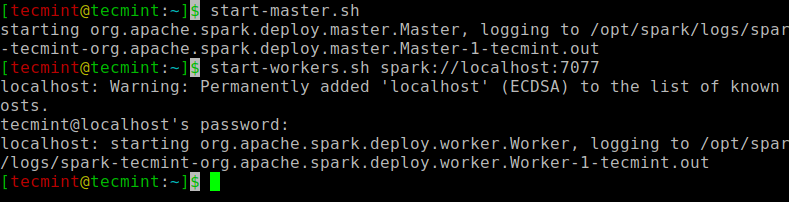
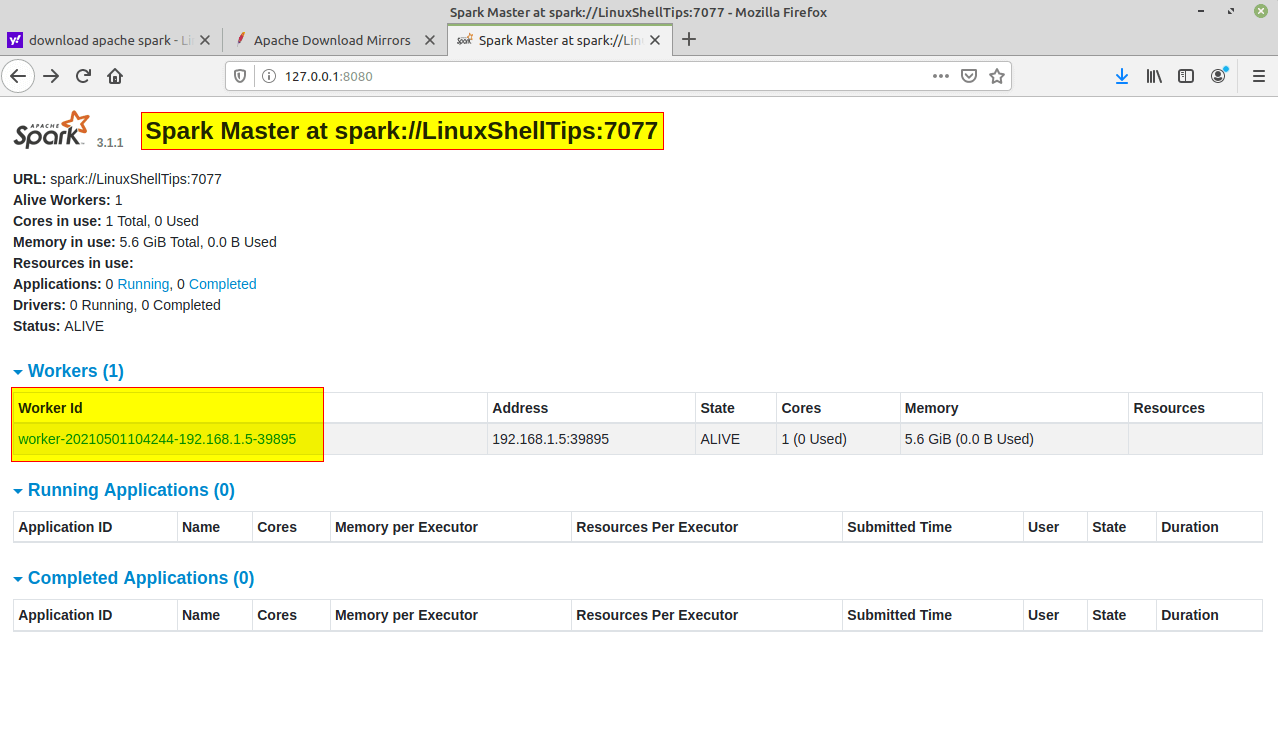
Once the service is started go to the browser and type the following URL access spark page. From the page, you can see my master and slave service is started.
http://localhost:8080/
OR
http://127.0.0.1:8080
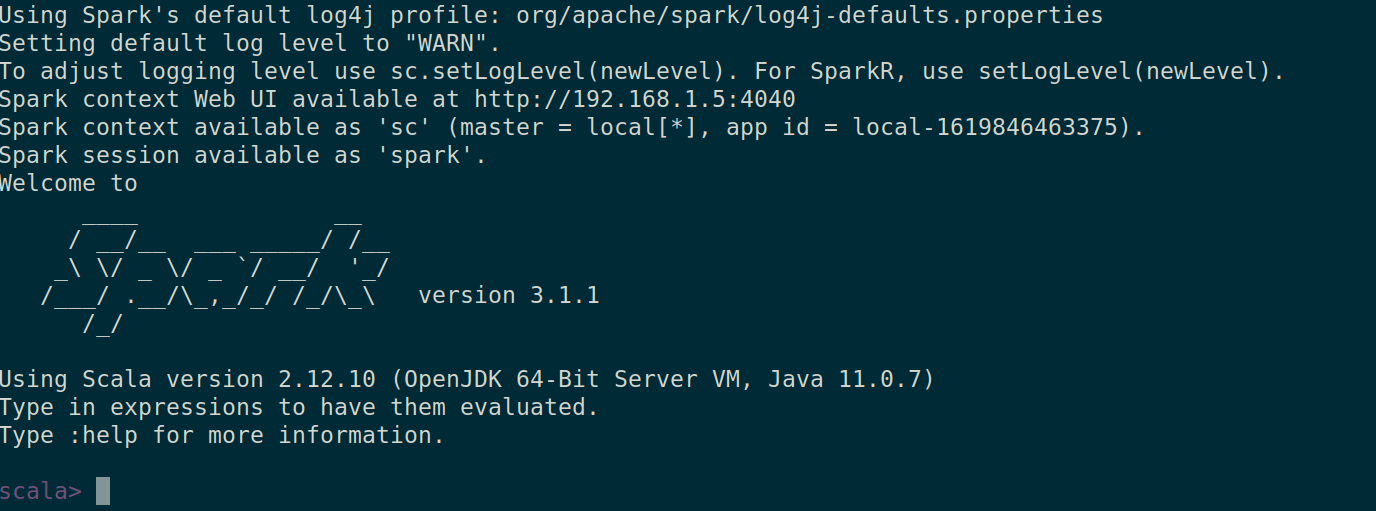
You can also check if spark-shell works fine by launching the spark-shell command.
$ spark-shell
That’s it for this article. We will catch you with another interesting article very soon.

Installing Apache Spark on Ubuntu becomes a useful learning exercise because it helps connect distributed computing concepts with a real working environment. Setting up the dependencies correctly also provides a stronger foundation for experimenting with Spark before moving to larger production systems.
The installation is successful but seeing below issue, I can see HDFS file:
warning: there was one feature warning; re-run with -feature for details
Found 4 items
drwxr-xr-x – hadoop supergroup 0 2021-07-14 10:51 /anil
drwxrwxrwx – hadoop supergroup 0 2021-07-13 23:19 /data
drwxrwxr-x – hadoop supergroup 0 2021-07-13 00:57 /tmp
drwxr-xr-x – hadoop supergroup 0 2021-07-13 00:09 /user
res2: Int = 0
while reading from hdfs in spark
scala> spark.read.csv("/data/orders/").show(10)
org.apache.spark.sql.AnalysisException: Path does not exist: file:/data/orders;
  at org.apache.spark.sql.execution.datasources.DataSource$$anonfun$org$apache$spark$sql
$execution$datasources$DataSource$$checkAndGlobPathIfNecessary$1.apply(DataSource.scala:576)
  at org.apache.spark.sql.execution.datasources.DataSource$$anonfun$org$apache$spark$sql
$execution$datasources$DataSource$$checkAndGlobPathIfNecessary$1.apply(DataSource.scala:559)
  at scala.collection.TraversableLike$$anonfun$flatMap$1.apply(TraversableLike.scala:241)
  at scala.collection.TraversableLike$$anonfun$flatMap$1.apply(TraversableLike.scala:241)
  at scala.collection.immutable.List.foreach(List.scala:392)
  at scala.collection.TraversableLike$class.flatMap(TraversableLike.scala:241)
  at scala.collection.immutable.List.flatMap(List.scala:355)
  at org.apache.spark.sql.execution.datasources.DataSource.org$apache$spark$sql$execution
$datasources$DataSource$$checkAndGlobPathIfNecessary(DataSource.scala:559)
  at org.apache.spark.sql.execution.datasources.DataSource.resolveRelation(DataSource.scala:373)
  at org.apache.spark.sql.DataFrameReader.loadV1Source(DataFrameReader.scala:242)
  at org.apache.spark.sql.DataFrameReader.load(DataFrameReader.scala:230)
  at org.apache.spark.sql.DataFrameReader.csv(DataFrameReader.scala:641)
  at org.apache.spark.sql.DataFrameReader.csv(DataFrameReader.scala:487)
  ... 49 elided